Module 01 · Introducing NoSQL
Reading: Vector Databases向量数据库
Vector databases, a newer NoSQL database, are rapidly becoming popular with the exponential increase in the use of Large Language Models (LLMs), such as OpenAI's GPT. But what is a vector database? Here's how IBM defines a vector database:
向量数据库是一种较新的 NoSQL 数据库,随着大型语言模型(LLMs)如 OpenAI 的 GPT 的使用呈指数级增长,正迅速变得流行。但什么是向量数据库?以下是 IBM 对向量数据库的定义:
A vector database is designed to store, manage, and index massive quantities of high-dimensional vector data efficiently.
向量数据库旨在高效地存储、管理和索引海量高维向量数据。
Source: https://www.ibm.com/topics/vector-database
来源:https://www.ibm.com/topics/vector-database
Next, learn about data as vectors.
接下来,学习数据作为向量的概念。
Vectors 向量
You can transform text, images, audio, and video into vectors, also known as vector data, using embedding functions based on various methods, including machine learning models, word embeddings, and feature extraction algorithms.
您可以使用基于各种方法的嵌入函数,包括机器学习模型、词嵌入和特征提取算法,将文本、图像、音频和视频转换为向量,也称为向量数据。
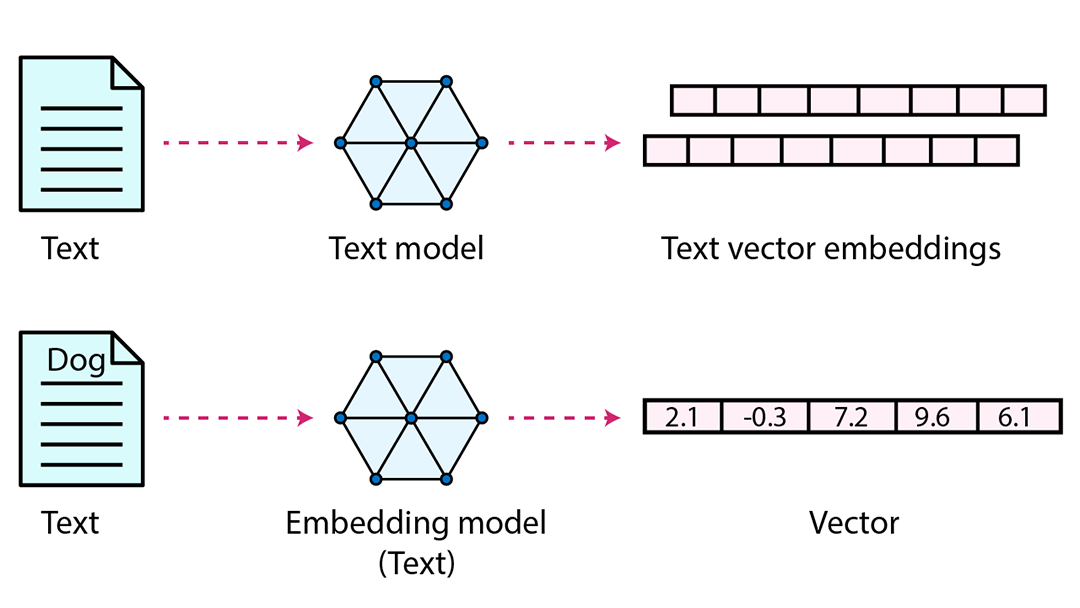
For example, the vector representation of dog is [2.1,-0.3, 7.2, 9.6, 6.1]
例如,狗的向量表示为[2.1,-0.3, 7.2, 9.6, 6.1]
Similar words for dogs include the word canine or K9, so a vector database will identify both terms and include the same vector values.
狗的相似词汇包括犬或 K9,因此向量数据库将识别这两个术语并包含相同的向量值。
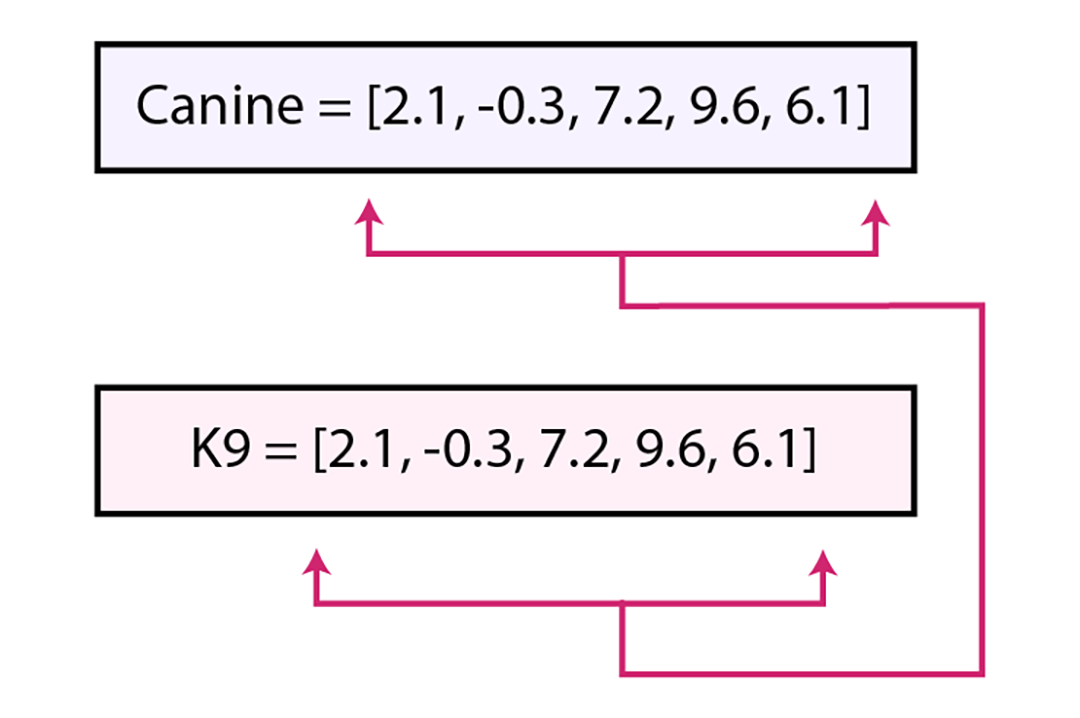
Important! When words have relationships or similar contexts, but the meaning is not identical, these words have vectors that are closer together within the database that help identify the relationship.
重要提示!当词语具有关系或相似的语境,但含义并不完全相同时,这些词在数据库中的向量会彼此靠得更近,从而有助于识别它们之间的关系。
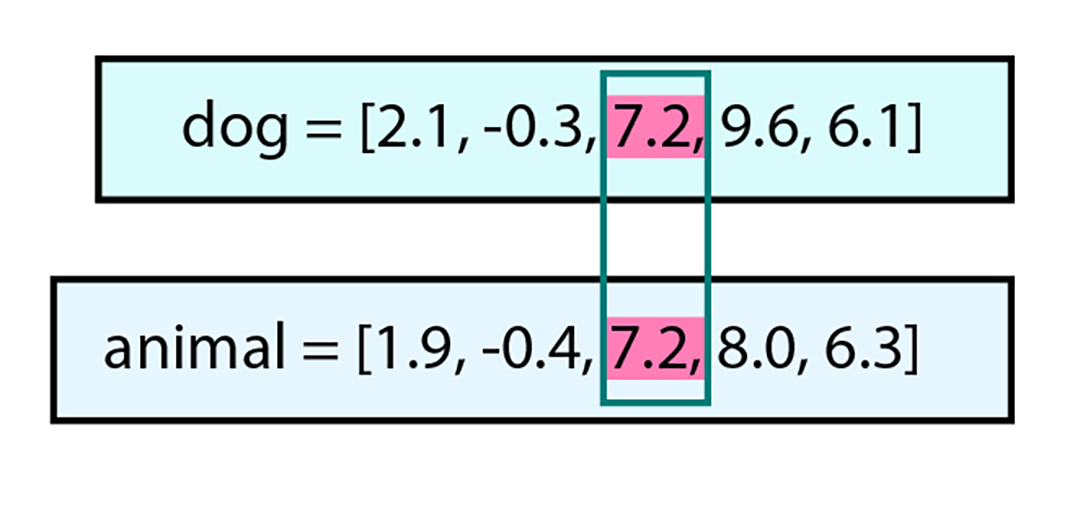
For example, you'll see the word animal represented as [1.9, -0.4, 7.2, 8.0, 6.3]
例如,你会看到动物这个词表示为[1.9, -0.4, 7.2, 8.0, 6.3]
Each numeric value you see displayed inside of a vector is one dimension.
你看到的向量中显示的每个数值代表一个维度。
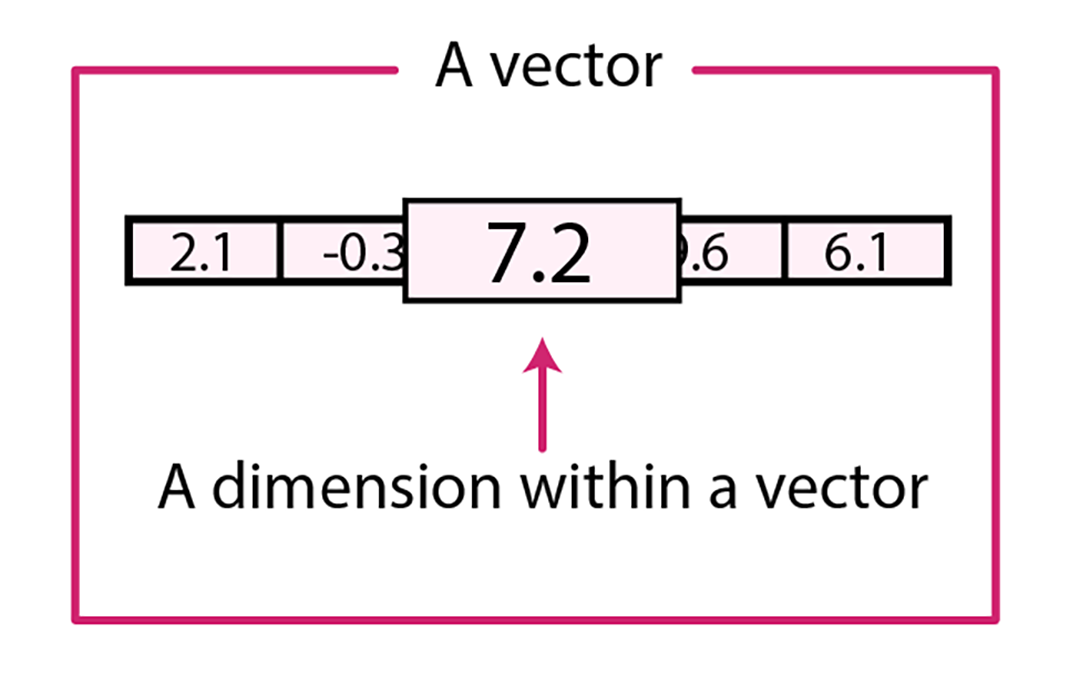
Vectors can have a few or thousands of dimensions, depending on the granularity and complexity of the classification required.
向量的维度可以有几个或成千上万个,这取决于分类所需的粒度和复杂性。
Returning to the example of a dog classifications, we know a dog is an animal, but not all animals are dogs. The relevance and relationships between the words "dog" and "animal" mean that these words will be much closer together as vector values and within the database itself. The following illustration shows the one dimension, dimension 7.2, that the word dog and animal share.
回到狗分类的例子,我们知道狗是一种动物,但并非所有动物都是狗。"狗"和"动物"这两个词之间的相关性和关系意味着,在向量值和数据库本身中,这些词会彼此靠得更近。以下插图显示了狗和动物共享的一个维度,即维度 7.2。
Next, explore why companies are moving to vector databases.
接下来,探讨公司为何转向向量数据库。
Vector Database benefits 向量数据库的优势
In contrast to conventional techniques that involve querying databases for exact matches or predefined criteria, a vector database empowers you to discover the most similar or related data by considering their semantic or contextual significance.
与需要查询数据库进行精确匹配或预定义标准等传统技术不同,向量数据库通过考虑其语义或上下文意义,使您能够发现最相似或相关数据。
In other words, unlike other database types that require an exact term search, you can use a vector database to conduct similarity searches and retrieve data according to their vector distance or likeness.
换句话说,与其他需要精确术语搜索的数据库类型不同,您可以使用向量数据库进行相似性搜索,并根据其向量距离或相似性检索数据。
For example, you can use a vector database to perform the following tasks:
例如,您可以使用向量数据库执行以下任务:
- Recommend TV shows to watch based on your current viewing habits.
根据您当前的观看习惯推荐要观看的电视剧。 - Locate related products based on the first product's features and ratings when shopping online.
根据首个产品的特性和评分,在在线购物时定位相关产品。
Because related vector data exists mathematically closer to each other within the database, search and data delivery times are faster. So rather than having to perform additional analysis techniques to retrieve related data, the trained model and vector database delivers relevant search results faster.
由于相关向量数据在数据库中数学上彼此更接近,因此搜索和数据传输时间更快。因此,无需执行额外的分析技术来检索相关数据,训练好的模型和向量数据库就能更快地提供相关的搜索结果。
Popular Vector Databases 流行的向量数据库
Database offerings and their features are changing concurrently with the exponentially fast speed of AI development. Before selecting a vector database, you'll want to review its applicability to your data and LLM. Next, check out these currently popular vector databases:
数据库的提供及其特性正随着 AI 发展的指数级速度同步变化。在选择向量数据库之前,您需要评估其与您的数据和 LLM 的适用性。接下来,请查看这些目前流行的向量数据库:
Chroma 色度
Chroma is an open source embedding database with which you can perform the following tasks:
色度是一个开源的嵌入数据库,您可以使用它执行以下任务:
- Store embeddings and their metadata
存储嵌入及其元数据 - Embed documents and queries
嵌入文档和查询 - Search embeddings 搜索嵌入
Pinecone
Pinecone provides long-term memory for high-performance AI applications. Pinecone emphasizes the following capabilities and features:
Pinecone 为高性能 AI 应用提供长期记忆。Pinecone 强调以下能力和特性:
- Runs as a fully managed service
作为完全托管的服务运行 - Provides high scalability
提供高可扩展性 - Provides real-time data ingestion
提供实时数据摄取 - Delivers low-latency search
提供低延迟搜索
Weaviate
Weaviate, an open-source vector database that stores data objects and vector embeddings from machine-learning models, is said to provide the following capabilities and features:
Weaviate 是一个开源的向量数据库,用于存储机器学习模型中的数据对象和向量嵌入,据称提供以下功能和特性:
- Provides efficient similarity searches
提供高效的相似性搜索 - Scales to store and process billions of data objects
可扩展以存储和处理数十亿数据对象 - Runs the GraphQL API 运行 GraphQL API
- Provides real-time updates
提供实时更新
Recap 回顾
After completing this reading, you know that:
完成本阅读后,你知道:
- Vector databases store, manage, and index massive quantities of high-dimensional vector data efficiently.
向量数据库能够高效地存储、管理和索引海量高维向量数据。 - You can transform text, images, audio, and video into vector data.
您可以将文本、图像、音频和视频转换为向量数据。 - Vector data consists of a series of numbers known as dimensions.
向量数据由一系列称为维度的数字组成。 - Vector databases store Items with similar or "like" vector numbers closely together within the database
向量数据库将具有相似或"类似"向量数字的项目在数据库中紧密地存储在一起。 - Chroma, Pinecone, and Weaviate are three popular vector databases
Chroma、Pinecone 和 Weaviate 是三个流行的向量数据库
Ready to learn more? Get in-depth information at the following IBM websites:
准备好了解更多信息吗?请访问以下 IBM 网站获取深入信息:
IBM.com: What is a vector database?
IBM.com:什么是向量数据库?
The IBM Engineering and Scientific Subroutine Library: Vectors
IBM 工程与科学子程序库:向量